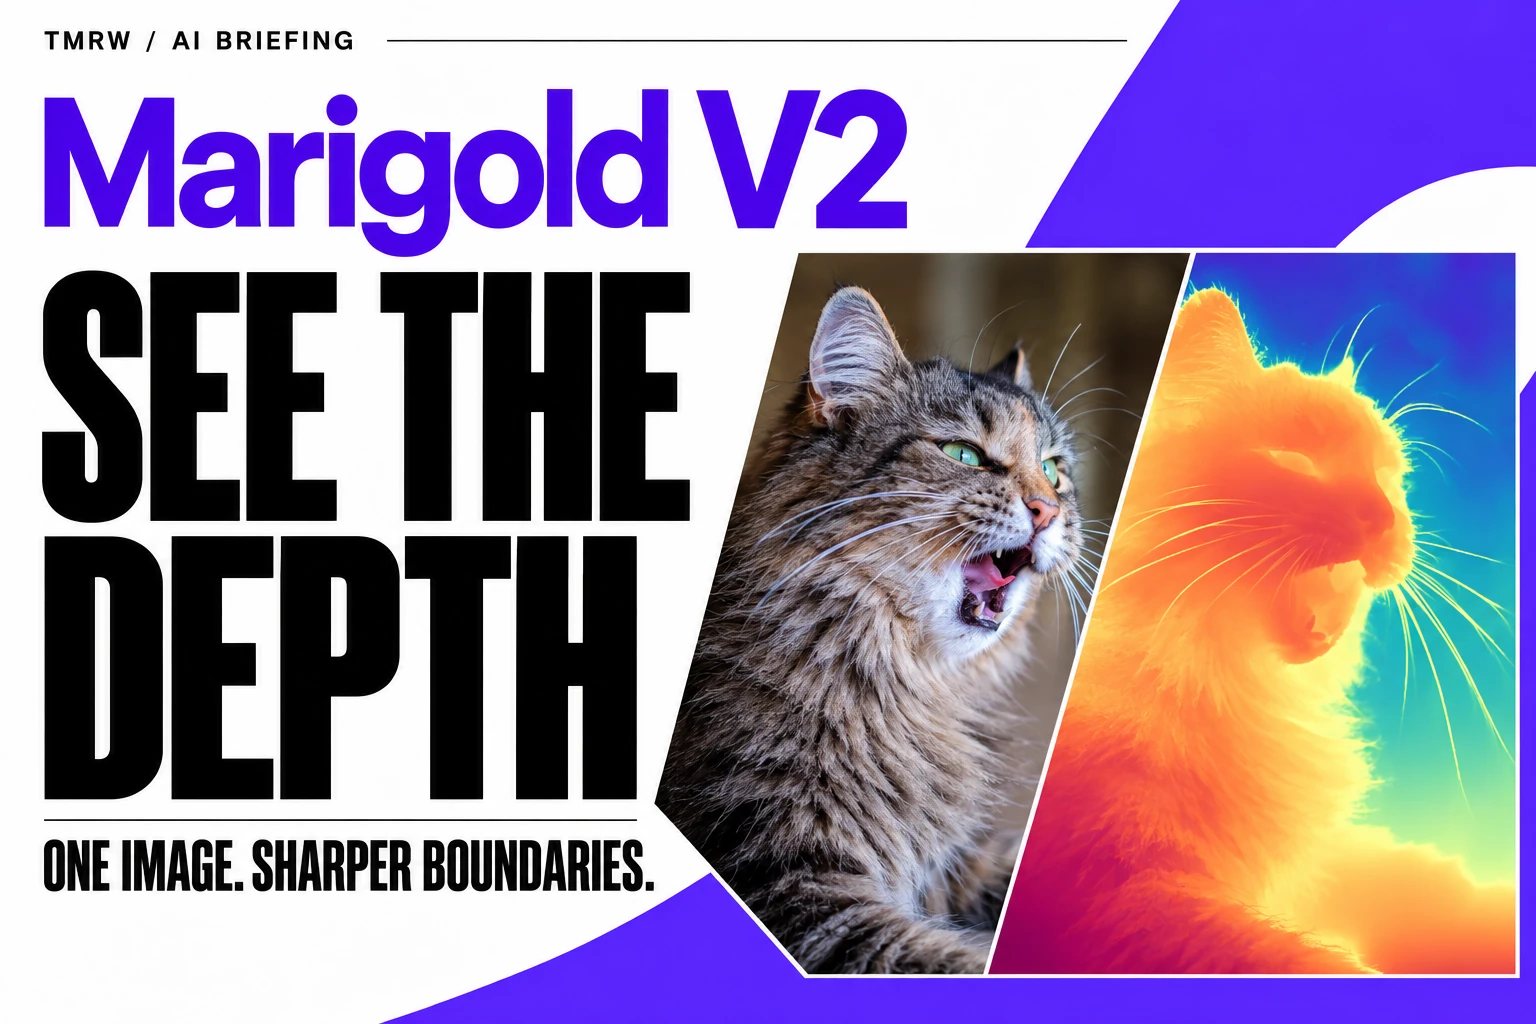
Cover: AI-generated editorial illustration by TMRW, inspired by the Marigold V2 paper’s depth examples. Source material.
Marigold V2, a research paper published on September 8 and highlighted by AI Weekly on September 9, takes an image-generation model and adapts it to estimate depth from a single picture. The researchers report a 16–26% improvement in absolute relative error over the previous best on KITTI and ETH3D, two evaluation datasets.
That makes it relevant to people working with scene reconstruction and image effects. The interesting development is that a model trained to generate imagery can also provide a starting point for estimating the structure inside an image.
From making pictures to reading their structure
A depth map assigns distance-related values to image locations. For a visual-effects workflow, the useful question may be whether a foreground subject separates cleanly from its background. Fine edges matter: a result that looks plausible at thumbnail size can become visibly wrong around hair or foliage.
The paper describes adapting a diffusion transformer for single-step inference, with training changes intended to improve sharpness and behavior on unfamiliar inputs. The benchmark percentages refer to a specific error measure on particular datasets. They do not mean every image is 26% better, or that all downstream applications improve by the same amount.
The accessible training claim
In an author's release note, the team describes adapting Qwen-Image-Edit-2509 with quantization and a relatively small trainable adapter on a single 32 GB consumer GPU. The author also points to public code, weights and a demonstration. That is a claim about the adaptation recipe, not about training the original image model from scratch on one graphics card.
The distinction matters when assessing how reproducible a result might be. A small lab can benefit from work already embedded in a pretrained model while still depending on that model's access conditions, computational requirements and limitations. The project repository is the place to begin checking what an actual reproduction would require.
A useful test starts with your difficult images
Our suggested evaluation would use a fixed set of images drawn from the intended workflow, including examples where the current method fails. Inspect boundaries at the size used in the final output. Record runtime, memory use and the amount of manual correction needed. A cleaner benchmark result is encouraging; less correction on your own material is a reason to change a pipeline.
Also separate a visually convincing estimate from a measurement you can rely on for physical distance. Before using any output in a system that needs scale, establish what the model returns and how that output is calibrated. A depth-colored image by itself cannot settle that question.
We have read the paper abstract, release notes and repository, rather than run the model. Our assessment is that Marigold V2 is a worthwhile candidate for a controlled comparison, especially where thin boundaries make existing results expensive to repair. The release supplies a research lead. Your own failure cases should decide whether it becomes a tool.